Data Engineer / SDE — Data Platforms

Akash Singh

I build reliable data platforms, pipelines, and developer tools. Currently working with large-scale data systems — experience across BigQuery, Spark, Databricks, Python & SQL.

01 Featured Projects

A few things I've built end-to-end — problem, architecture, and the interesting decisions along the way.

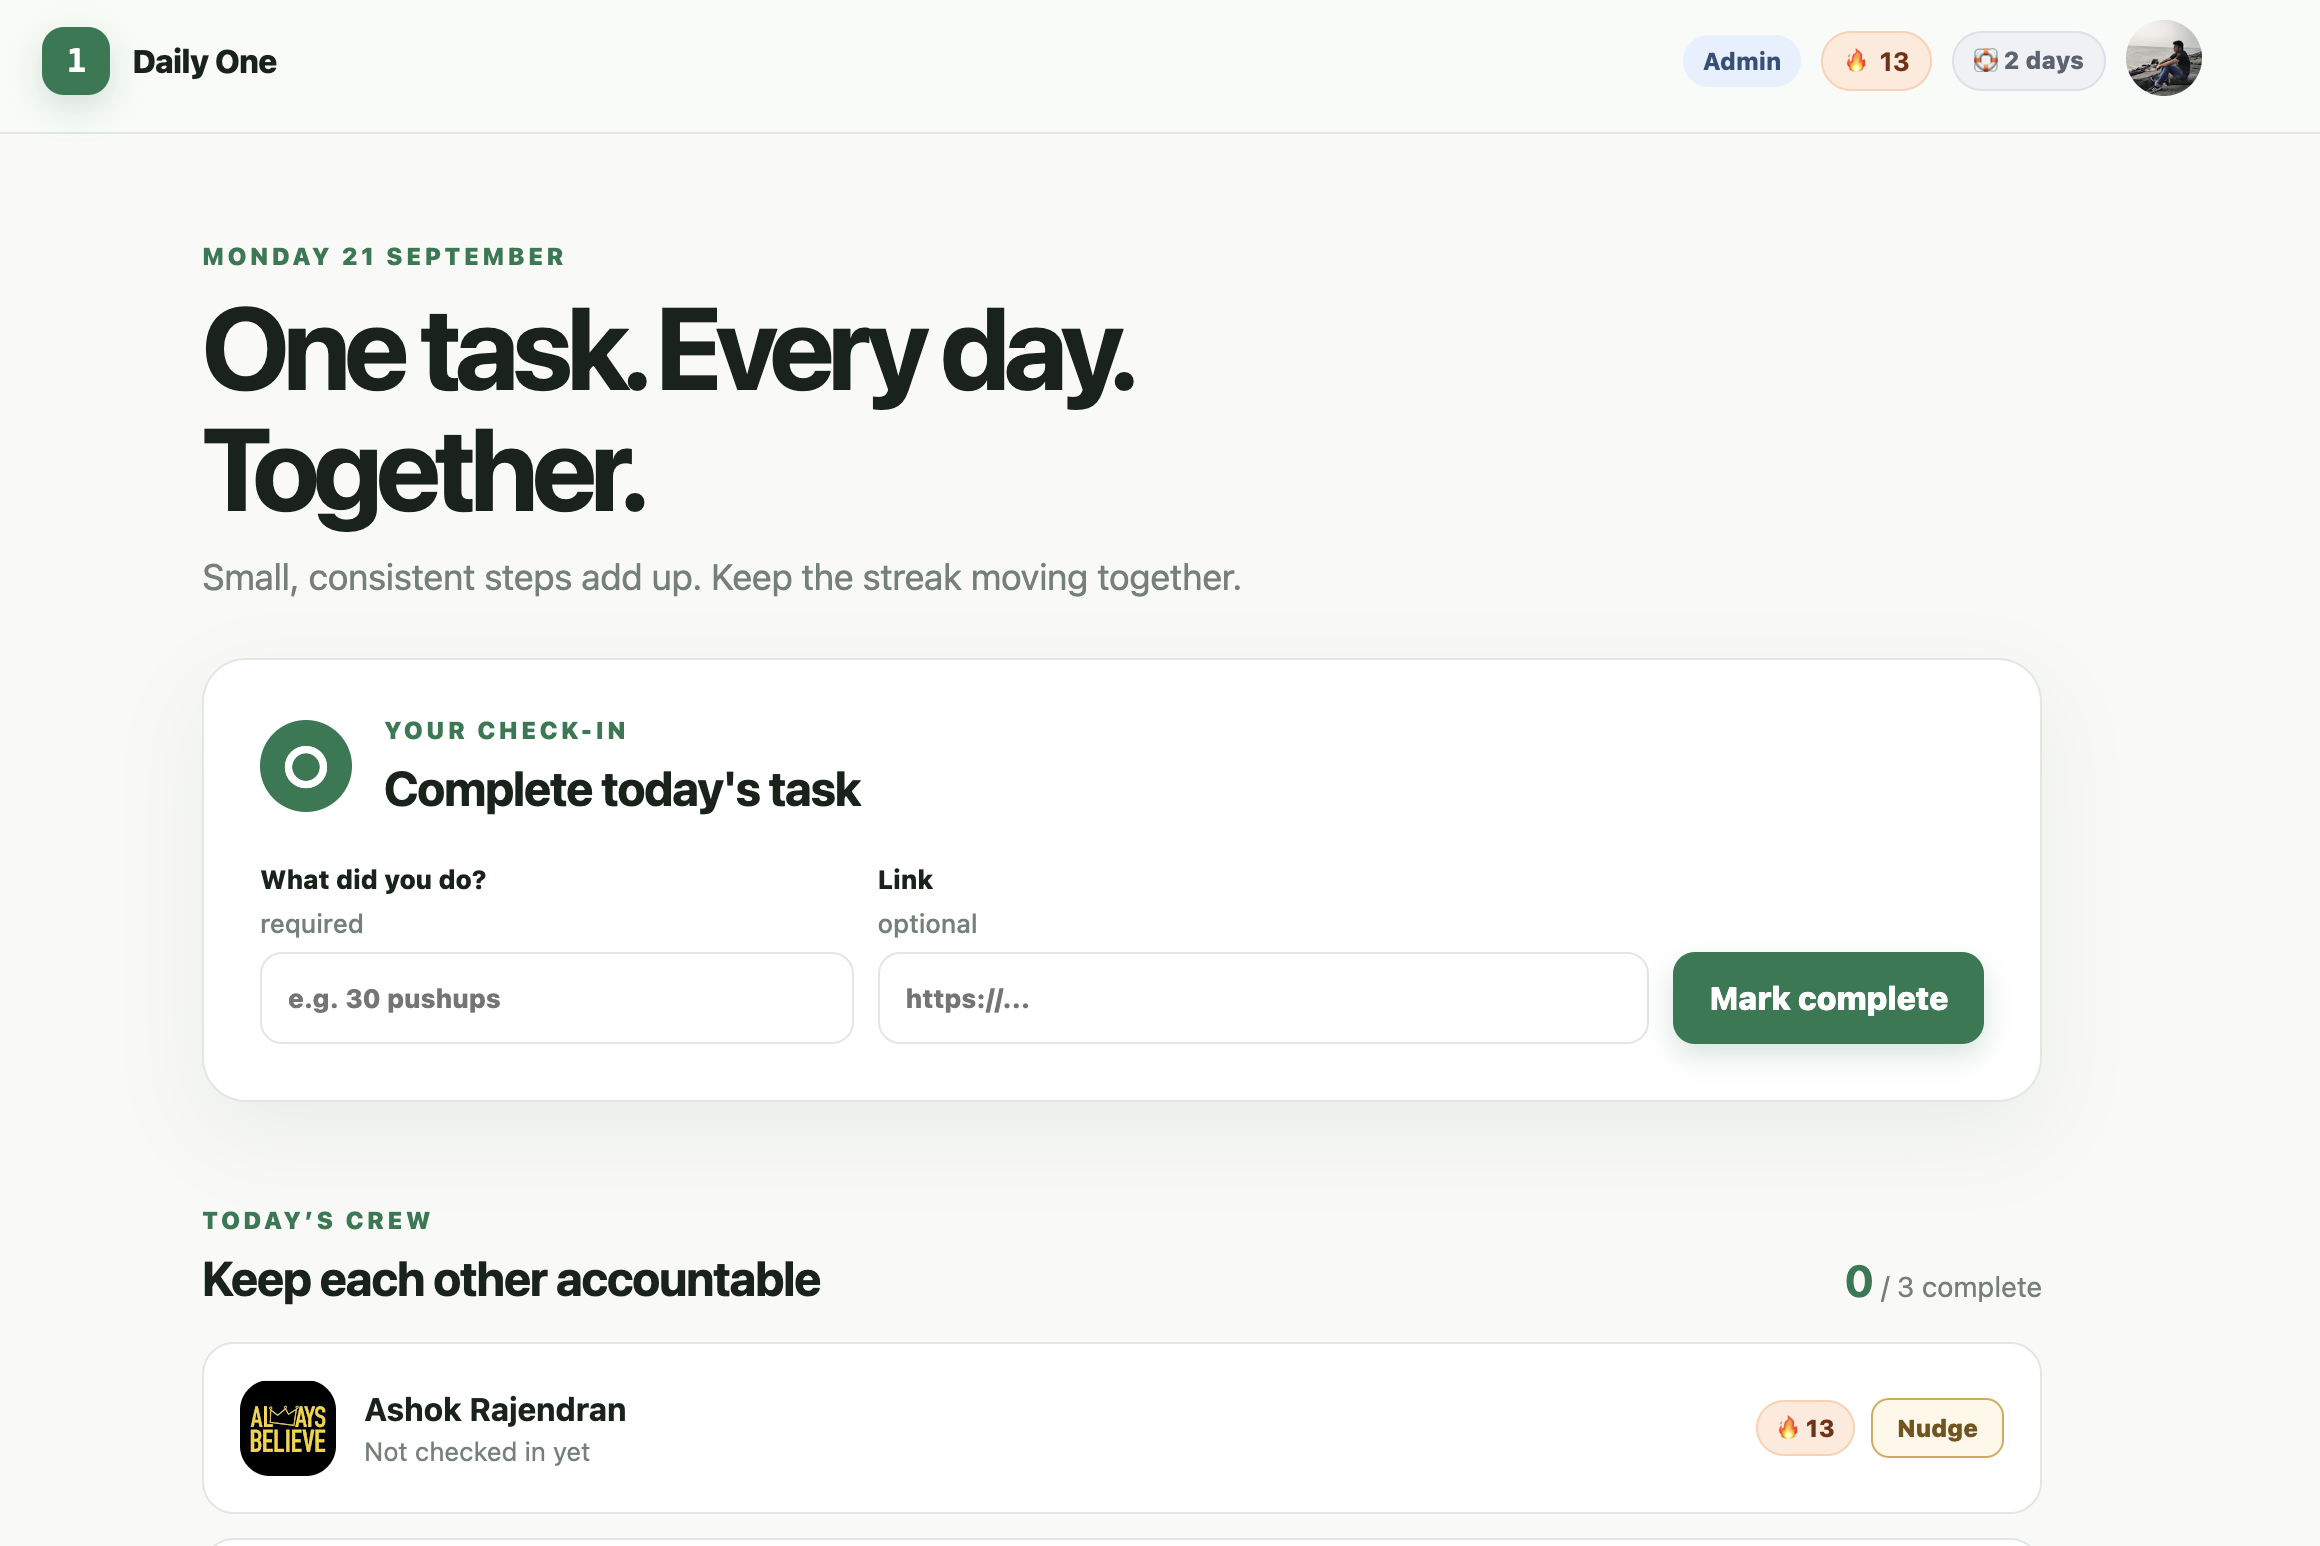
Daily One app screenshot

Daily One

Live

A personal accountability & streak app that keeps one important habit on track every day.

Read the engineering story

Problem

Habit trackers get abandoned because they demand too much. I wanted a dead-simple daily commitment with real streak accountability.

Solution

A focused web app: one daily task, streak logic, and reminders — nothing else competing for attention.

Architecture

Containerized web app served behind Cloudflare Tunnel on my home server, alongside the rest of S7 Labs. (TODO: fill exact stack — e.g. framework, DB, auth provider.)

Interesting challenges

Modeling streaks correctly across time zones and missed days; keeping auth/session handling simple but secure.

Auth

Authenticated access with per-user state. (TODO: name the authN/authZ approach — session cookies, OAuth, etc.)

Result

Running in daily use on daily-one.s7labs.dev.
DockerCloudflare TunnelWeb appAuth
Athena Research Platform screenshot

Athena Research Platform

In progress

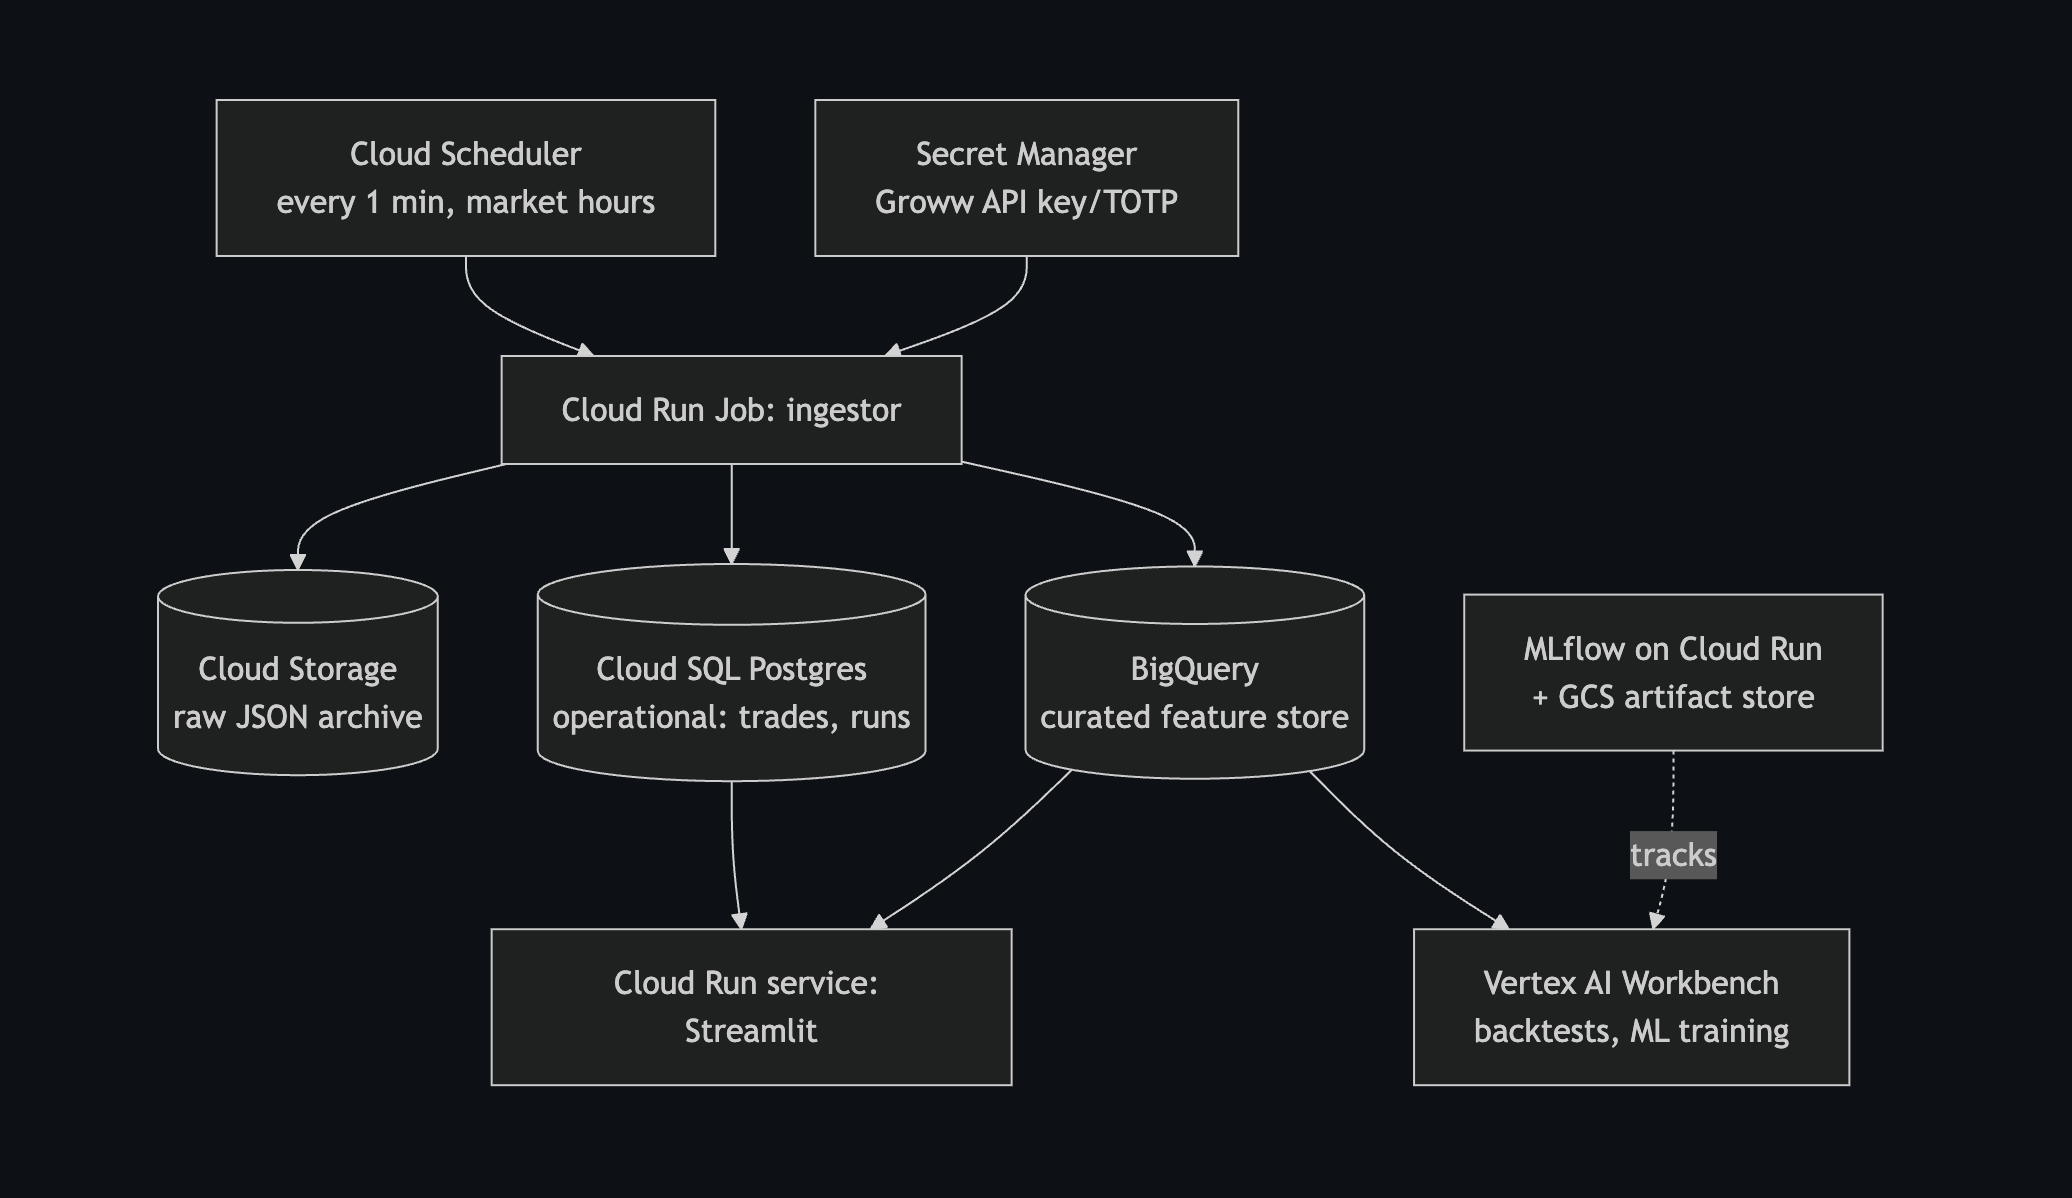
A research platform for collecting market data, generating signals, backtesting strategies and evaluating performance — engineering-first, not a trading bot.

Read the engineering story

Problem

Intraday market research needs clean, causal data and a repeatable way to test ideas — most retail tooling leaks future information or can't be reproduced.

Data ingestion

Polling/API-based ingestion with an automatic mock mode when credentials are absent, plus layered fallbacks across data sources so a single provider outage doesn't stop research.

Storage & features

Feature functions are causal by construction (no look-ahead) and versioned, with an ingested_at distinct from event time to track leakage.

Signal & backtesting

A weighted signal model scores each indicator into a composite; ridge-regression tuning fits forward-return weights and stores append-only model snapshots for auditability.

Interesting decisions

Strict separation of paper-trading from any execution; graceful degradation when a broker plan lacks historical/options APIs.

Result

Data platform + monitoring dashboard shipped; signal model + retraining in progress.

PythonStreamlitSQLiteTime-seriesML (ridge)
Internet
   │
Cloudflare  (edge TLS, WAF, DNS)
   │
Cloudflare Tunnel  (zero-trust, no open ports)
   │
Home Server  (Ubuntu · s7labs.dev)
   │
Docker
   ├── Portfolio      (this site)
   ├── Daily One      (accountability app)
   ├── Immich         (self-hosted photos)
   └── Other services

S7 Labs — Home Lab

Running

A physical home server running my personal services in Docker, exposed safely to the internet through Cloudflare Tunnel — no inbound ports opened.

Read the engineering story

Problem

I wanted to self-host real applications (this portfolio, a photo library, side projects) on my own hardware without exposing my home network.

Solution

An Ubuntu box running everything in Docker, published via Cloudflare Tunnel so ingress is zero-trust — the origin never listens on a public port.

Networking

Cloudflare edge terminates TLS and handles DNS for s7labs.dev; the tunnel maps hostnames to local container ports over HTTP internally.

Security hardening

SSH bound to localhost only (systemd socket activation), tunnel-only exposure, and per-service scoping — reducing the public surface to just the tunnel.

Interesting challenges

Correct tunnel origin scheme (HTTP vs HTTPS), socket-activated SSH quirks, and keeping services isolated.

Result

Multiple services running reliably behind one domain — this page is served from it.

DockerCloudflare TunnelUbuntunginxZero-trust

02 Engineering Experience

Outcome-oriented highlights. No proprietary architecture, queries, or company-internal data.

Data Engineer / SDE II (Data Platforms)

Best Buy India Apr 2025 — Present

Data Platform Modernization

Consolidated disconnected analytical datasets into a single governed platform on BigQuery and redesigned expensive queries into cheaper, faster ones.

+40%Faster reporting
−25%Lower compute / slot use
50+Internal consumers served
  • Platformized AI-powered self-service tooling (conversational analytics, virtual assistants) into reusable internal services — cutting ad-hoc requests and manual analyst effort.
  • Built and optimized CI/CD with GitHub Actions across dev & prod for safe, repeatable rollouts.
  • Designed an audit-trail / point-in-time history framework for compliance-grade historical reporting.

Data Engineer

Shell India Markets Oct 2021 — Apr 2025

Streaming & Warehousing at Scale

Built distributed streaming pipelines and a scalable cloud data warehouse on Azure & Databricks, with reusable ingestion frameworks.

−40%Query times
−25%Pipeline latency
+40%Delivery efficiency
  • Engineered real-time pipelines with Data Factory, Databricks, Delta Live Tables & Spark Streaming — improving fault tolerance.
  • Automated monitoring, alerting & ops with Azure Functions, Logic Apps & Log Analytics.
  • Designed parameterized multi-source ingestion in Python, SQL & PySpark for reuse across teams.

03 Case Studies

Not "here's what I built" — "here's a hard problem and how I approached it." Details are generalized to avoid anything proprietary.

Reducing BigQuery query cost & runtime

−25% slots

Problem

Core analytical queries were scanning far more data than needed and consuming excessive slots, driving up both runtime and cost.

Investigation

Profiled query plans and job stats to find the hotspots — full-table scans, wide reads, and redundant transformations repeated across dependent queries.

Approach

Introduced partitioning & clustering on high-selectivity keys, pruned unnecessary columns, restructured queries to push filters down early, and removed duplicated transformation stages.

Result

~25% reduction in slot consumption and runtime on the targeted workloads, with faster downstream reporting.

What I learned

Partitioning helps only when queries actually filter on the partition key — schema and query design have to be co-designed. Next time I'd bake cost/scan checks into CI earlier.

Latest-per-key dedup without blowing the memory limit

Query that finally ran

Problem

A large dedup kept failing with "resources exceeded" — analytic window sorts buffered entire partitions per worker.

Investigation

Traced it to QUALIFY ROW_NUMBER() OVER (PARTITION BY key ORDER BY ts) patterns; the limit is per-worker, so splitting into temp tables didn't help a single oversized partition.

Approach

Rewrote the latest-per-key dedup as a top-1 heap using ARRAY_AGG(STRUCT(...) ORDER BY ts DESC LIMIT 1)[OFFSET(0)] — keeping one row per key in memory instead of the whole partition. Only the large-table dedups were converted; tiny dimension tables stayed simple.

Result

The query completed reliably; the memory ceiling was no longer the bottleneck.

What I learned

Window functions are convenient but hide huge memory costs on skewed/large partitions. Aggregation-based rewrites are worth the extra verbosity at scale.

04 S7 Labs

Things I build outside work — experiments, self-hosted apps, and infrastructure I actually run.

Home Server

Running

Ubuntu box running all personal services in Docker on my own hardware.

Cloudflare Tunnel

Running

Zero-trust ingress for s7labs.dev — no inbound ports opened at home.

Immich

Running

Self-hosted photo library replacing cloud photo storage.

Daily One

Running

Accountability/streak app I use daily (see Projects).

Athena

Experimental

Market-data research platform & signal experiments (see Projects).

SSH hardening

Running

SSH bound to localhost via systemd socket activation; reachable only through the tunnel.

05 Tech Stack

Languages

  • Python
  • SQL

Data

  • Spark
  • PySpark
  • BigQuery
  • Databricks
  • Delta Lake

Cloud / Infrastructure

  • GCP
  • Azure
  • Docker
  • Terraform
  • Cloudflare

Tools

  • Git
  • GitHub
  • Power BI

06 Certifications & Recognition

07 About Me

I'm a data engineer who enjoys understanding systems beyond the layer I work on. That curiosity is why I ended up running my own home server, self-hosting applications, and building side projects around problems I personally run into.

Away from the keyboard I'm into football, chess, staying active in the gym, and building random things just to see how they work.

08 Get in touch

Want to talk data, infrastructure, or interesting engineering problems?